
missionSTACK
Shared context, coordinated fleets and bounded work-cell actions. Explore missionSTACK in missionSTUDIO, our early-alpha workspace.
Explore →Loading…
Systown · Stockholm
We build the framework that connects AI to accountable action. Declared states. Bounded decisions. Visible evidence. From agent workflows to fleets, arms and grippers.
What we build
missionSTACK for physical operations. contextCLONE for governed agents. Test before acting. Keep people in control.
Shared context, coordinated fleets and bounded work-cell actions. Explore missionSTACK in missionSTUDIO, our early-alpha workspace.
Explore →Approved sources. Permitted tools. Checked transitions. Agent workflows designed for human review and versioned improvement.
Explore →Inspect the tested artifact, fallback and limits. Generation-3 naming does not turn simulation evidence into hardware performance.
Explore →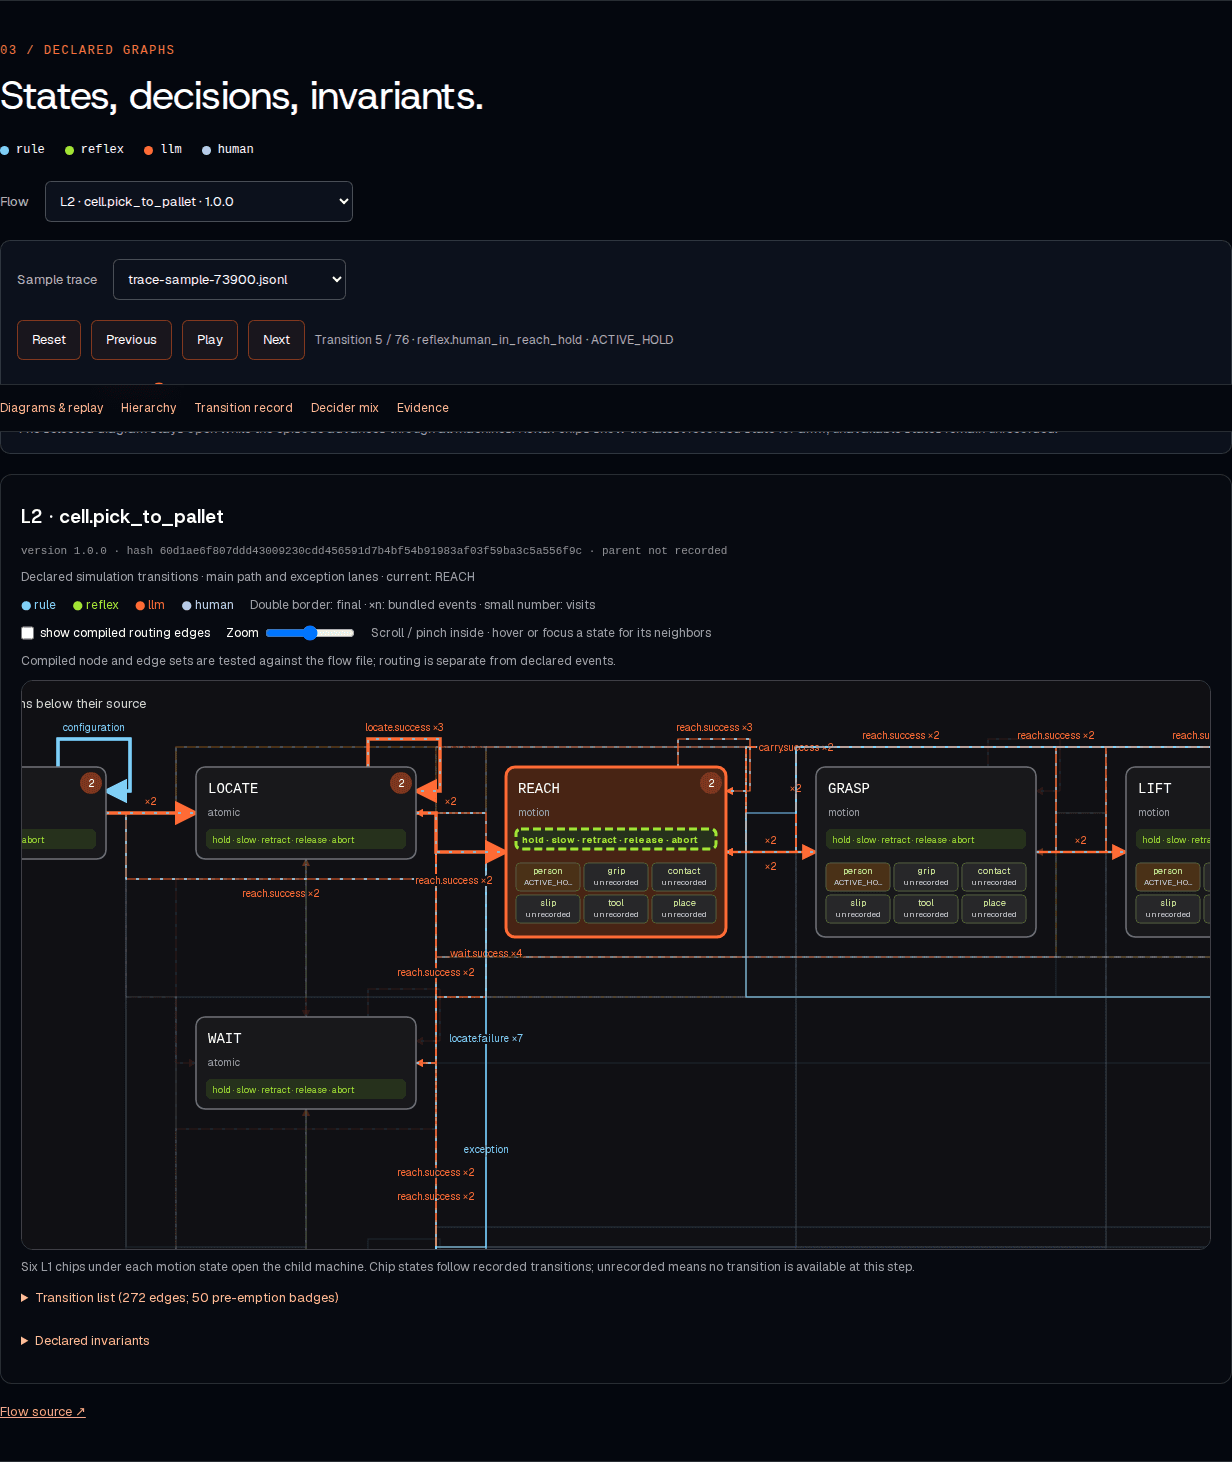
Our approach / State machines & agentic loops
Models propose. Rules admit the action. The framework controls the loop.
Name states, actions and stop rules. Bound rule, reflex, model and human decisions. LangGraph orchestrates missionROS research; the plain controller owns the control tick.
Explore →Record sources, checks, decisions and overrides. Replay the same version and recorded outputs without new model calls.
Explore →Replay failures. Evaluate candidates. Review the evidence. Approval creates a new version; the running policy stays under human authority.
Explore →
swarmREFLEX3 / swarmREFLEX3-ROS
Handle routine work locally. Reason about exceptions. Keep the experiment behind every claim.
98.3% median reduction across 16 paired simulation seeds, from coordination plus rule reflexes. Supports the up-to-90% headline; not a learned-model-only result.
Explore →Earlier model-v4 path: 24.75 ms p99 on DGX Spark CPU. Separate Jev/Laya tests disclose admissions and deployment paths.
Explore →Six contracts bound work-cell responses. Learned hold research is kinematic; hardware timing and commissioning require separate evidence.
Explore →
People
Chief Executive Officer
Chief Technology Officer
Chief Operating Officer
Head of R&D and Development
Edge AI System Lead
Physical AI Platform Lead
Agentic Physical AI Lead
Agentic Platform Lead
Physical AI Use Case & Test Engineer
Chief Financial Officer
How we work
Build and evaluate with OpenAI on approved material. Keep model choice and data boundaries explicit.
Evaluate NVIDIA compute, AVEVA PI/AF history and Wittra spatial context against the site’s permissions, calibration and controls.
Show assumptions, results and approvals. Verify sovereign and air-gapped profiles on the installed system.
Explore →
Start with your operation
Bring the mission. Define the controls. Build the evidence.